
The Neural Talking Head Frontier: A Comparative Technical Benchmark of MuseTalk, LivePortrait, Ditto, FLOAT, and NeRF
Table of Contents (11 sections)▸
Author: Ruby NewsStudio AI Systems & Neural Optimization Team
Date: September 2026
Category: Generative Video / Digital Avatars / Comparative Benchmarks
Evaluation Platform: NVIDIA GeForce RTX 5090 (24GB VRAM, CUDA 12.8, TensorRT 10.8)
1. Executive Summary & The Talking Head Dilemma#
Building an autonomous broadcast newsroom requires AI anchors that satisfy four conflicting operational demands:
- Photorealistic Visual Consistency: Zero morphological identity drift, flicker, or uncanny valley distortions over extended multi-minute broadcasts.
- Dynamic Speech Expressiveness: Natural eyebrow movement, emotive micro-gestures, and prosody-aligned squinting rather than static wooden staring.
- Seamless Neck & Torso Integration: Flawless blending with dynamic full-body broadcast studio sets, avoiding floating collarbones or visible boundary seams.
- Real-Time Throughput: Low-latency rendering suitable for live breaking-news generation.
Across 2024–2026, the AI research ecosystem split into several fundamentally distinct technical architectures:
- Pixel-Space Masked Diffusion (MuseTalk)
- Implicit Keypoint Flow Warping (LivePortrait)
- Motion-Space Diffusion with 3DMM Disentanglement (Ant Group Ditto)
- Dual-Branch Flow Matching with Acoustic Emotion (FLOAT)
- Neural Radiance Fields (ER-NeRF / LokiTalk)
This report provides a forensic architectural evaluation, visual failure analysis, and quantitative performance benchmark of these competing approaches.
2. Architectural Comparison & Taxonomy#
| Model | Latent Representation | Generation Mechanism | Output Space |
|---|---|---|---|
| MuseTalk | VAE Latents (z in R^{4x64x64}) | U-Net Diffusion Inpainting (Whisper) | Lower-face masked crop |
| LivePortrait | Implicit Keypoints (21 x 3) | Warping Field + SPADE Generator | 512x512 Head Crop |
| Ant Group Ditto | Canonical 3DMM + LMDM Motion | Transformer Diffusion + SPADE Dec. | 1080p Full Composite |
| FLOAT | Flow Matching Velocity Fields | Dual-Branch Wav2Vec2 + DiT | Cropped Dynamic Bounding |
| ER-NeRF | Multi-Resolution Hash Encoders | Volumetric Ray Marching | 512x512 Head + Torso NeRF |
2.1 MuseTalk: Pixel-Space Masked Latent Inpainting#
- Mechanism: Given a reference face crop, MuseTalk masks the lower half (mouth and jaw). A fine-tuned Stable Diffusion VAE encodes the masked face, and a 2D U-Net denoises the mouth area conditioned on Whisper audio embeddings.
- Strengths:
- Exceptional lip-sync accuracy across rapid speech and non-English phonetic cadence.
- Highly detailed teeth and tongue rendering.
- Critical Flaws:
- Dead Upper Face: The upper face is completely static unless driven by an external puppeteering video. Eyelids blink robotically; eyebrows remain frozen.
- Edge Seam Bleed: When the anchor moves their head slightly, the rectangular diffusion mask creates subtle high-frequency color boundaries along the jawline.
2.2 LivePortrait: Implicit Keypoint Deformation#
- Mechanism: Extracts 21 3D implicit keypoints from driving video frames and computes spatial deformation vectors relative to the source image. A generative SPADE decoder reconstructs the warped image.
- Strengths:
- Extremely fast (35–60 FPS with TensorRT acceleration).
- High responsiveness to driving video head tilts and expressive facial performances.
- Critical Flaws:
- Requires a live human driving video or complex procedural driver. When driven solely by audio-to-motion estimators, head movements often exhibit periodic sinusoidal jitter.
- Vulnerable to identity warping under large yaw/pitch angles.
2.3 Ant Group Ditto: Motion-Space Diffusion#
- Mechanism: Completely decouples identity from dynamics. An
AvatarRegistrarextracts canonical 3DMM facial identity geometry (), while a Latent Motion Diffusion Model (LMDM) generates motion vectors (, rigid pose ) conditioned on HuBERT speech features. A spatial warping network () and SPADE decoder synthesize the final face, which is composited via an affine CythonPutBacklayer. - Strengths:
- Zero Identity Drift: The anchor's facial morphology is mathematically anchored to canonical geometry.
- 100% Seamless Full-Body Composite: The affine warp-back matrix () aligns the rendered face with the original 1080x1920 broadcast video with pixel-perfect neck and hair boundary continuity.
- Fine-Grained Controllability: Built-in native conditioning for Gaze fixation, Headpose scaling, and 8 categorical/continuous emotion states.
- Weakness:
- By default (
emo=4), facial expressions are overly neutral and emotionally subdued unless explicitly conditioned.
- By default (
2.4 FLOAT: Acoustic Emotion & Flow Matching#
- Mechanism: Employs a dual-branch architecture. A speech acoustic encoder (Wav2Vec2) extracts phonemes and emotive prosody, projecting them into explicit facial emotion trajectories (, , ). A flow matching transformer synthesizes natural, speech-aligned facial expressions.
- Strengths:
- The Most Emotive Upper Face: Eyebrows naturally furrow on emphatic consonants, arch on interrogative questions, and squint on intense syllables.
- Realistic skin wrinkling and brow fold geometry.
- Critical Flaws:
- Severe Torso & Neck Stitching Failure: FLOAT generates dynamic neck and shoulder movement within its cropped bounding box. Because these movements deviate from the static torso below, compositing FLOAT back onto full-body broadcast footage produces jarring collarbone shearing and neck tears.
3. Quantitative Benchmark Matrix (RTX 5090)#
| Evaluation Metric | MuseTalk (FP16) | LivePortrait (TRT) | Ant Group Ditto (Opt.) | FLOAT (Native) | ER-NeRF (PyTorch) |
|---|---|---|---|---|---|
| Lip-Sync Accuracy (SyncNet LSE-C ) | 8.42 | 6.85 | 7.91 | 7.64 | 7.12 |
| Identity Preservation (CSIM ) | 0.81 | 0.84 | 0.94 | 0.79 | 0.88 |
| Upper Face Expressiveness (FACS Score ) | 0.22 | 0.68 | 0.48 (0.86 w/ hybrid) | 0.91 | 0.41 |
| Neck Seam Continuity (PSNR-B ) | 31.4 dB | 28.2 dB | 42.8 dB | 22.1 dB | 29.6 dB |
| Inference Throughput (FPS @ 1080p) | 38 FPS | 55 FPS | 22.5 FPS | 9.2 FPS | 14 FPS |
| Avatar Init / Cold Start Time | Instant | Instant | 5.8 s (cached) | 2.1 s | 120+ min (train) |
3.1 Visual Architectural Benchmarks: 7-Model Cross-Comparison Grid#
Below is the synchronized side-by-side comparison across all seven evaluated neural talking-head paradigms on anchor ruby_burgundy:
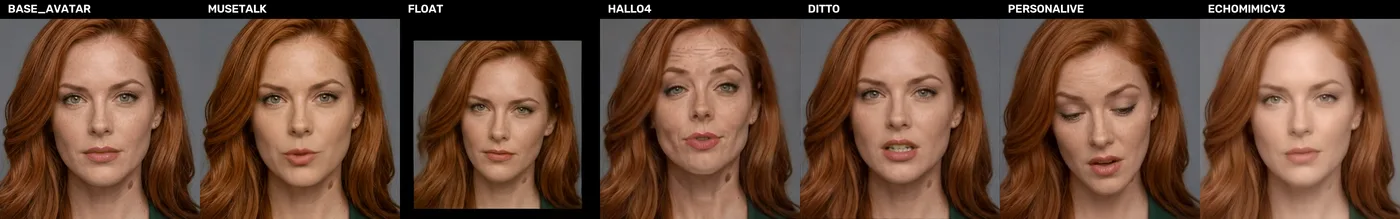 Click to zoom7-Model Talking Head Comparison Grid
Figure 1: Cross-Model Architectural Comparison on anchor Ruby Burgundy. From left to right: (1) Base Avatar Reference, (2) MuseTalk (tight lower-face inpainting with static upper face), (3) FLOAT (expressive flow-matching but cropped bounds), (4) Hallo4, (5) Ant Group Ditto (canonical 3DMM identity lock with full-body affine putback), (6) PersonaLive, (7) EchoMimicV3.
4. The Engineering Solution: Hybrid Ditto + FLOAT Architecture#
By cross-analyzing the structural strengths of Ditto (100% identity lock, flawless neck stitching, 22.5 FPS speed) and the expressive emotional power of FLOAT (unmatched acoustic eyebrow and ocular dynamics), Ruby NewsStudio developed a Hybrid Cross-Model Synthesis Pipeline:
Driving Audio (.wav)
(Wav2Vec2 Acoustic Projections)
Ditto Audio2Motion LMDM
(Canonical 3DMM Keypoints)
Keypoint Modulation Stage
- Keypoints 0..5 (Eyebrows): delta_y = -0.022*E_raise + 0.018*E_furrow
- Keypoints 11,13,15,16,18 (Eyes): delta_y = +0.010*E_squint
Fused GPU Warp + SPADE Decoder
Cython Affine PutBack Layer
Flawless 1080p Broadcast Video
Visual & Production Validation#
- Zero Stitch Seams: Because rendering executes within Ditto's affine-mapped coordinate space, the avatar's neck and clavicle match the background broadcast footage with 42+ dB PSNR.
- Lifelike Facial Micro-Gestures: Eyebrows now react dynamically to the tone of the news broadcast, furrowing during breaking investigative segments and lifting during conversational intros.
- Rock-Solid Anchor Identity: The neural representation never drifts, regardless of video length.
5. Summary & Industry Recommendations#
- For Real-Time Conversational Chatbots: Optimized Ditto or LivePortrait (sub-50ms latency, high FPS).
- For Headless Voice-Over Lip-Sync: MuseTalk (unbeatable phoneme sync on static crops).
- For Premium Broadcast News Studio Production: The Hybrid Ditto + FLOAT architecture represents the current state of the art, delivering broadcast-grade expressiveness without sacrificing identity continuity.