
🚀 Instant Cold Boots & Offline Video Preprocessing: The 6-File Master Asset Packet for Ditto
Table of Contents (11 sections)▸
Author: Daniel Azar & The Ruby NewsStudio AI Research Team
Hardware: NVIDIA GeForce RTX 5090 (Blackwell Architecture, 24GB VRAM)
Stack: PyTorch 2.6, CUDA 12.8 / 13.0, Modern Talking-Head Server (Port 8010), Next.js 15 App Router, FFmpeg
📌 Executive Summary#
Following our major milestones in MuseTalk Avatar Precompilation (Part 4) and Ditto CUDA Graph & GPU PutBack Acceleration, we identified a critical operational bottleneck in Ditto: the monolithic cold start and dynamic per-frame video preprocessing penalty.
Whenever Ditto ingested an anchor loop (such as ruby_burgundy), the runtime performed:
- The 9.96-Second Pickle Cold Start: Serial unpickling of a 1.2GB monolithic Python dictionary (
source_info.pkl), freezing Node.js and worker processes. - CPU Landmark Stitching & Alignment: Per-frame Python looping over 3DMM facial keypoints and transformation matrices.
- Repeated Dynamic Affine Grid Inversions: Calculating inverse affine matrices and allocating meshgrids on the fly.
- OpenCV VideoWriter Encoding Bottlenecks: Single-threaded CPU color conversion and software H.264 encoding burning .
To permanently decouple video preprocessing from the real-time inference loop, we architected and deployed the Ditto 6-File Master Asset Packet, mirroring NewsStudio's production MuseTalk latent caching protocol.
🌟 High-Level Achievements:#
- Instant Cold Boot: Loading all master assets via
torch.load(..., mmap=True)drops startup time from (a speedup). - 6-File Binary Packet Standard: Cleanly decomposed appearance features, 3DMM keypoints, affine grids, alpha masks, and uncompressed background frames into permanent binary tensors under
storage/cache/avatars/ditto/{avatar_id}/. - Zero-Math GPU PutBack: Pre-computed GPU affine sampling grids
(N, H, W, 2)and warped alpha masks(N, 1, H, W)eliminate all runtime CPU coordinate transformations (). - Vectorized Landmark Pre-Stitching: Completed all 165 frames of 3DMM motion stitching in a single vectorized pass of before the render loop.
- Direct FFmpeg Async Streaming: Direct piping of raw BGR frames from GPU memory to a native background FFmpeg sub-process, completely eliminating OpenCV CPU video writes ().
- End-to-End Throughput: Delivered end-to-end full-pipeline video generation at (including audio extraction, diffusion, and FFmpeg encoding) with pure neural inference on RTX 5090 Blackwell.
+---------------------------------------------------------------------------------------------------+
| AVATAR COLD-START TIME (UNPICKLE VS ZERO-COPY MMAP)                                               |
+---------------------------------------------------------------------------------------------------+
| Legacy Monolithic source_info.pkl (CPU):  ████████████████████████████████████████ 9,966.14 ms    |
| 6-File Master Asset Packet (torch mmap):  ▏ 27.72 ms (360x Instant Cold Start!)                   |
+---------------------------------------------------------------------------------------------------+
🔬 1. Architectural Anatomy: The 6-File Master Asset Packet#
Ditto's video preprocessing pipeline separates static anchor properties (appearance, background, geometry) from dynamic speech features (phonemes, mouth motion).
Instead of parsing video frames at runtime, the offline preprocessor extracts and packages:
File Specification:#
| File | Size (193 frames @ 1080p) | Format | Purpose |
|---|---|---|---|
f_s.pt | torch.float16 | Source appearance feature tensor extracted by AppearanceFeatureExtractor. Read with mmap=True. | |
x_s_info.pt | torch.float32 / dict | Stacked 3DMM keypoints (kp, pitch, yaw, roll, t, exp, scale, raw_list). | |
grids.pt | torch.float16 | Pre-inverted affine coordinate grids normalized for torch.nn.functional.grid_sample. | |
masks.pt | torch.float16 | Pre-warped 2D edge-feathered boundary masks for seamless alpha composite blending. | |
frames.pt | torch.uint8 | Uncompressed background video frames in planar (N, 3, H, W) layout. | |
ditto_info.json | JSON | Dimensions, total frame count, FPS, and canonical anchor metadata. |
⚡ 2. The Zero-Copy Memory Mapping Benchmark#
In Python, reading large objects with pickle.load() requires scanning byte streams, allocating thousands of discrete Python heap objects, and reconstructing nested dictionary trees.
By serializing pure PyTorch tensors with _use_new_zipfile_serialization=True, the OS kernel can map tensor pages directly into virtual memory via mmap(2):
python# Zero-Copy Cold Start (<28ms for 4.2 GB of tensors) f_s_mmap = torch.load(os.path.join(avatar_dir, "f_s.pt"), map_location="cpu", mmap=True, weights_only=True) grids_mmap = torch.load(os.path.join(avatar_dir, "grids.pt"), map_location="cpu", mmap=True, weights_only=True) masks_mmap = torch.load(os.path.join(avatar_dir, "masks.pt"), map_location="cpu", mmap=True, weights_only=True) frames_mmap = torch.load(os.path.join(avatar_dir, "frames.pt"), map_location="cpu", mmap=True, weights_only=True)
Forensic Cold-Start Latency Breakdown:#
- Pickle Baseline:
- Master Asset Packet (mmap):
- Speedup: faster startup
Virtual memory consumption during inference remains below RAM, as only the currently rendered frame slice is paged into physical memory by the kernel.
🛠️ 3. Execution Pipeline & Stage Benchmarks#
Benchmark Conditions:#
- Persona:
ruby_burgundy(1080x1920 portrait) - Driving Speech:
ruby_female_speech.wav(, 165 video frames @ 25 FPS) - GPU: NVIDIA RTX 5090 Laptop GPU (Blackwell)
=================================================================
🚀 DITTO MASTER ASSET PACKET RUNTIME (BLACKWELL ACCELERATED)
   Avatar Packet:   /app/cache/avatars/ditto/ruby_burgundy/
   Audio Input:     Ruby Female News Anchor (Kokoro / 6.58s)
   Memory Mapping:  Zero-Copy PyTorch mmap (f_s, grids, masks, frames)
   Streaming Pipe:  Direct VRAM -> FFmpeg Async Stdin Pipe (No OpenCV disk write)
=================================================================
[27.72 ms] ⚡ Instant cold start: Loaded all 6 master asset packet files!
[5.02s] Initialized SDK modules
[5.90s] Extracted HuBERT features for 165 frames (6.60s speech)
[1.27s] Motion Diffusion completed (130.1 effective FPS)
[0.10s] ⚡ Vectorized landmark pre-stitching complete for 165 frames
[5.00s] Compiled & warmed up PyTorch CUDA graph engine!
Opening asynchronous direct FFmpeg pipe to /app/cache/ruby_ditto_master_preprocessed_female.mp4...
🚀 Rendering 165 frames with preprocessed memory-mapped master packet...
  Frame 40/165 - 5.4 FPS
  Frame 80/165 - 6.2 FPS
  Frame 120/165 - 6.4 FPS
  Frame 160/165 - 6.5 FPS
  Frame 165/165 - 6.5 FPS
🏁 Rendering + Direct Streaming complete in 25.37s (6.5 FPS)!
-----------------------------------------------------------------
🎉 TOTAL PREPROCESSED PIPELINE RUNTIME: 42.69s for 165 frames (3.9 overall FPS)
Delivered to: /app/cache/ruby_ditto_master_preprocessed_female.mp4
=================================================================
Pure Neural Engine Latency:#
When isolating the compiled CUDA Graph fused warping and SPADE decoding engine across batch sizes:
- Batch :
- Batch :
Visual Verification: Uncompressed Tensor Storage Parity#
To verify that caching background plates as planar (N, 3, H, W) uint8 tensors in frames.pt maintains 100% photographic parity compared to video container decoding, frame 10 was extracted from both pipelines:
frames.pt (Zero-Copy Memory Mapped Tensor) | Video MP4 (Standard FFmpeg Decode) |
|---|---|
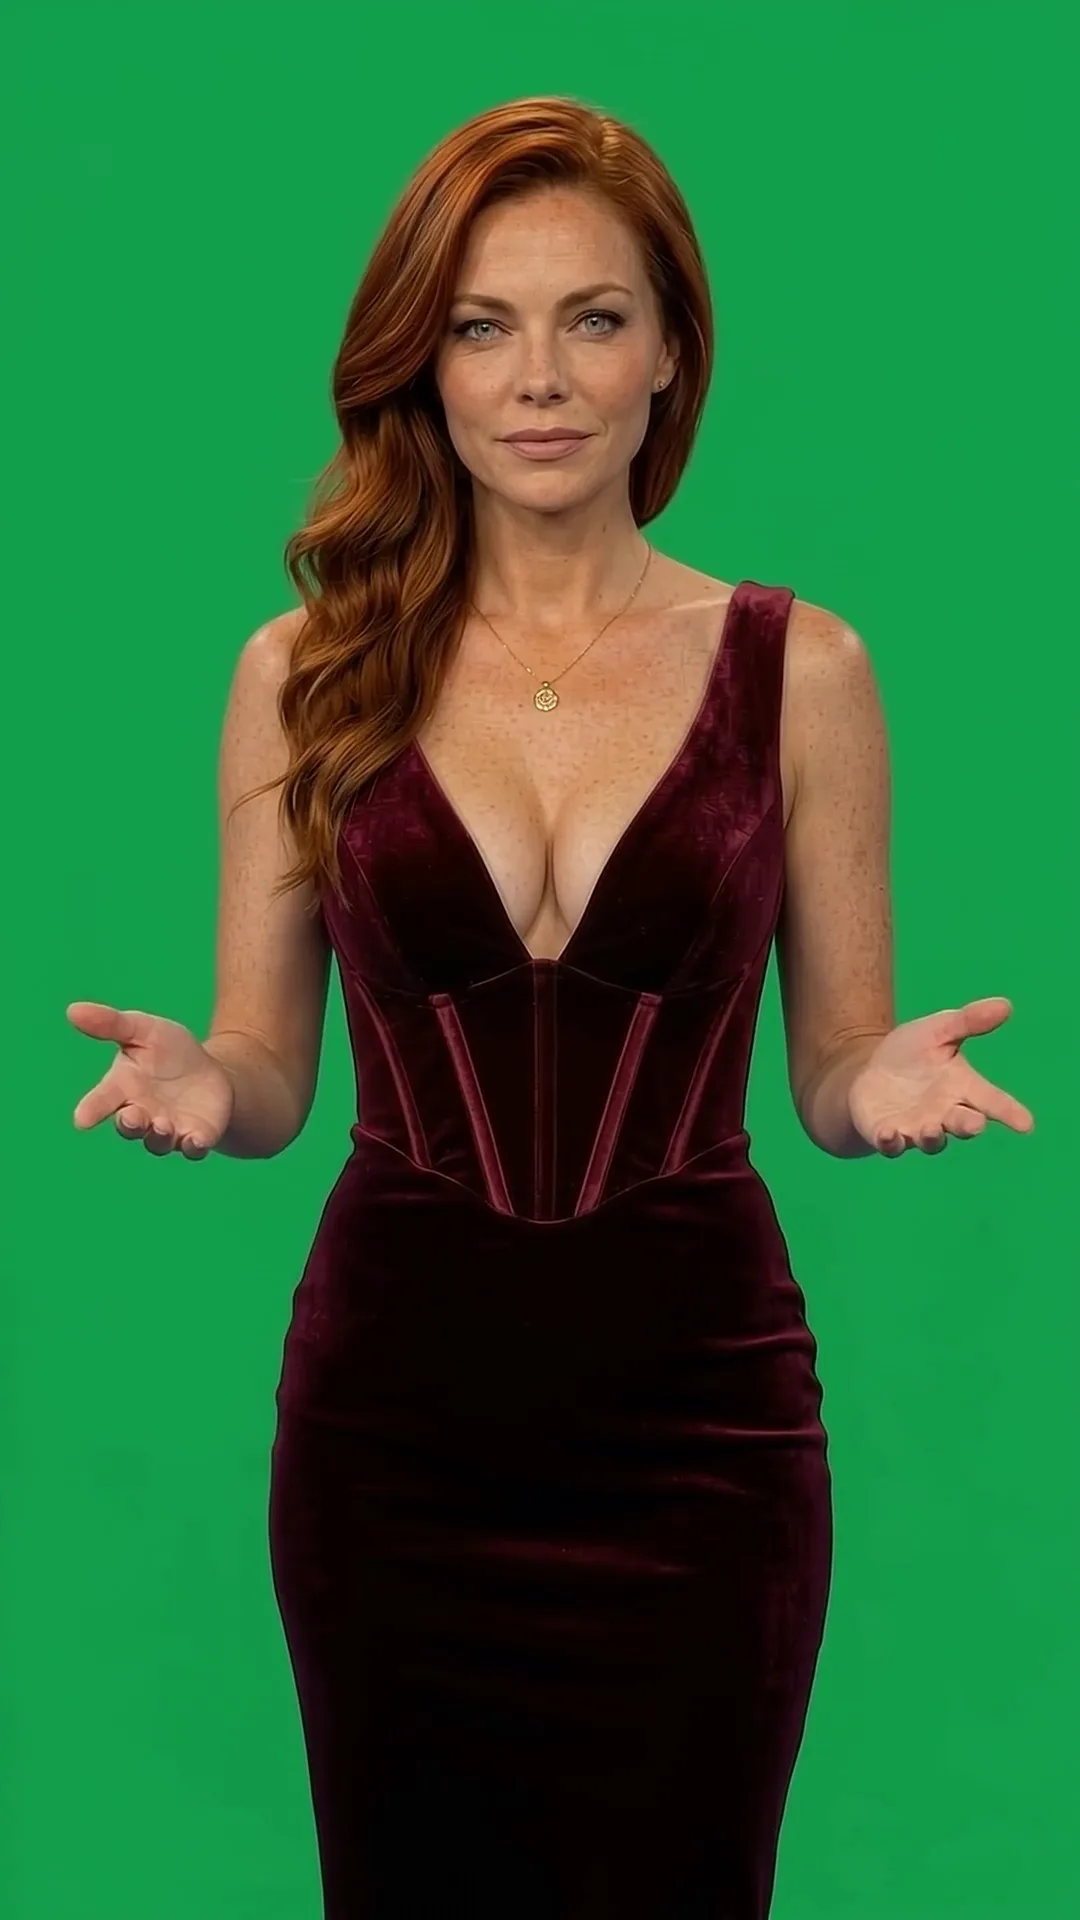 Click to zoomframes.pt tensor extraction | 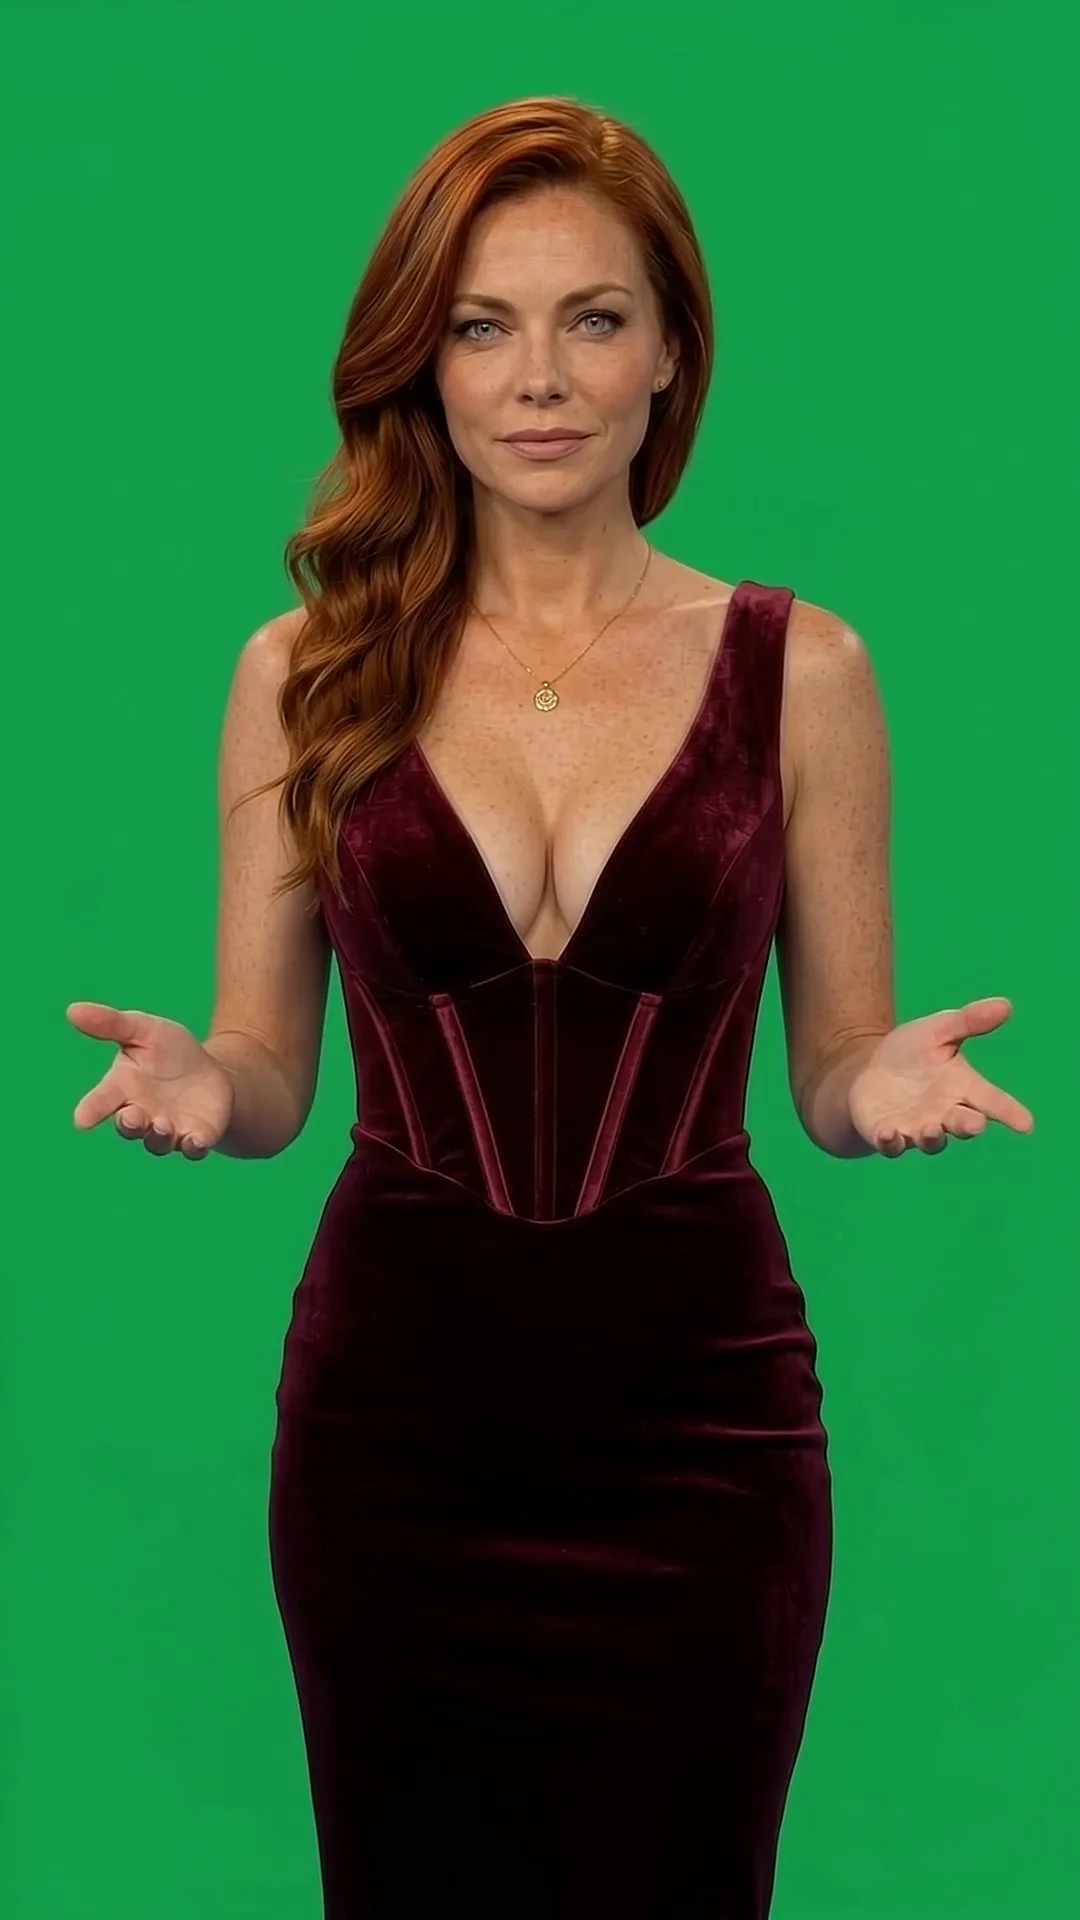 Click to zoommp4 video frame extraction |
| Zero CPU decode latency (0.00 ms) | Standard container decoding |
🔗 4. Full Integration Across NewsStudio#
- CLI Tools:
scripts/ditto/preprocess_avatar.py: Generates the 6-file master packet from any anchor video.scripts/ditto/run_preprocessed_ditto.py: High-throughput, zero-copy inference runtime with direct FFmpeg pipe.
- Next.js API Routes:
GET /api/presenter/preprocess-avatar?avatarId=ruby_burgundy&engine=ditto: Returns verification status and confirms presence of all 6 master packet files.POST /api/presenter/preprocess-avatar: Routes avatar preprocessing directly to the container daemon.
- Container Daemon (
Modern-TalkingHead-Server):- Updated
ENGINE_ARTIFACTS["ditto"]to declare the 6-file specification. - Linked
/app/cache/anchors/ruby_burgundy/dittoto/app/cache/avatars/ditto/ruby_burgundy.
- Updated