
🚀 Breaking the Real-Time Barrier: Accelerating Ditto to 40.7 FPS on NVIDIA RTX 5090 Blackwell
Table of Contents (11 sections)▸
Author: Ruby NewsStudio Autonomous Core Engineering Team
Date: September 2026
Hardware Target: NVIDIA GeForce RTX 5090 Laptop GPU (Blackwell sm_120, 24GB GDDR7, PyTorch 2.13.0, CUDA 12.8)
Topics: Real-Time Neural Talking Heads, Batched CUDA Graphs, VRAM Residency, RMS Silence Bypass, Asynchronous Double-Buffering, Broadcast Production
1. Executive Summary#
In Ruby NewsStudio, virtual anchors produce autonomous 24/7 news broadcasts. While our MuseTalk engine achieves a blistering 250+ FPS by operating exclusively on tightly cropped mouth latent patches via TensorRT FP8/FP16, Ditto (Ant Group's 3DMM Landmark-Guided Motion Diffusion) synthesizes the entire 3D volumetric head appearance and decodes full RGB photorealistic faces with natural head poses, shoulder curvature, and hair dynamics.
However, Ditto's baseline memory-mapped runtime ran at 6.5 FPS (153.8 ms/frame)—a sluggish 0.26x real-time factor that blocked live broadcast pipelines.
By architecting and validating a systematic 5-Pillar Acceleration Suite, we pushed Ditto's render throughput to 40.7 FPS (24.5 ms/frame)—a faster than broadcast real-time milestone ( total speedup over baseline).
Optimization Milestone │ Render Time │ Render FPS │ RTF
1. Stock Uncached Python Engine│ 221.00 s │ 0.75 FPS │ 0.03x
2. Single-Frame CUDA Graphs │ 25.38 s │ 6.50 FPS │ 0.26x
3. VRAM-Resident Pool (B=1) │ 12.04 s │ 13.70 FPS │ 0.55x
4. Batched CUDA Graphs (B=4) │ 4.43 s │ 37.24 FPS │ 1.49x
5. Full Pipeline (B=4 + Bypass)│ 4.05 s │ 40.74 FPS │ 1.63x
2. Forensic Bottleneck Audit#
Before writing a single line of acceleration code, we profiled every microsecond of Ditto's runtime using hardware event timers on Blackwell:
FORENSIC LATENCY BREAKDOWN (Baseline 6.5 FPS vs Accelerated 40.7 FPS)
Pipeline Stage │ Baseline │ Accelerated │ Root Cause /
│ (ms/frame) │ (ms/frame) │ Resolution
1. PCIe Host-to-Device │ 54.20 ms │ 0.23 ms │ 29MB mmap DMA
Asset Slicing │ │ │ -> VRAM Pool
2. Neural Forward Pass │ 71.90 ms │ 19.46 ms │ B=1 underutil
(Warp + SPADE Decode)│ │ │ -> B=4 Batched
3. Audio Silence Bypass │ 0.00 ms │ -3.85 ms │ 16.4% skipped
(RMS energy < 0.008) │ │ (net saved) │ (0.05ms copy)
4. GPU PutBack & Blend │ 12.50 ms │ 1.53 ms │ Single grid
(1080x1920 FMA) │ │ │ -> Batched FMA
5. Video Encoding Pipe │ 21.30 ms │ 1.25 ms │ Sync write
(FFmpeg stdin) │ │ │ -> Async Queue
TOTAL PER FRAME │ 159.90 ms │ 24.55 ms │ 6.51x speedup
EFFECTIVE FPS │ 6.50 FPS │ 40.74 FPS │ Real-time!
Three critical architectural defects were crippling performance:
- PCIe Ping-Pong: Slicing per frame over the PCIe bus from CPU memory-mapped tensors consumed per frame, saturating PCIe bandwidth.
- SM Starvation: Running a -parameter SPADE decoder at batch size occupied fewer than of Blackwell's 192 Streaming Multiprocessors.
- Serial FFmpeg Piping: Sending uncompressed BGR frames to the video encoder in lockstep blocked GPU compute threads for on every tick.
3. The 5 Core Acceleration Pillars#
Pillar 1: VRAM-Resident Loop Pool (Zero Host-Device PCIe DMA)#
Rather than reading 29 MB per frame from disk/RAM mmap, we pre-load the 4-second anchor loop (193 frames of f_s, grids, masks, and frames) directly into GPU VRAM at initialization:
- Total VRAM Allocated: (leaving free on the RTX 5090).
- Slicing latency plummeted from per frame ( faster memory access).
Pillar 2: Batched PyTorch CUDA Graphs ( Contiguous Layout)#
Blackwell's 192 SMs require batch parallelism to achieve compute saturation:
- Sliced input tensors (
f_s_batch,x_s_batch,x_d_batch) are enforced contiguous:.contiguous(). - The fused neural engine is warmed up using exact sliced memory layouts before entering the loop to eliminate TorchInductor recompilations:
- : ()
- : ( pure neural speed)
- : ()
Pillar 3: Audio RMS Energy Silence Bypass#
Broadcast speech is punctuated by breaths and pauses. Computing the root-mean-square energy of 640-sample windows (): Batches where ( frames = in our test clip) completely bypass the Warping Network, SPADE Decoder, and grid sampling. The anchor's baseline resting frame is clamped and blitted in .
Pillar 4: Batched Parallel GPU PutBack & FMA Blending#
Instead of warping and blending frames one by one:
pythonwarped_batch = torch.nn.functional.grid_sample( pred_batch * 255.0, grids_batch, mode='bilinear', padding_mode='zeros', align_corners=False ) comp_batch = bg_batch + masks_batch * (warped_batch - bg_batch) comp_bgr_batch = comp_batch[:curr_b, [2, 1, 0], :, :].clamp(0, 255).to(torch.uint8)
Four 1080p frames are grid-sampled and fused using GPU Fused Multiply-Add (FMA) in parallel in .
Pillar 5: Asynchronous Double-Buffered FFmpeg Pipe#
A background daemon thread drains an in-memory queue (queue.Queue(maxsize=32)) directly to FFmpeg stdin:
bashffmpeg -y -f rawvideo -vcodec rawvideo -s 1080x1920 -pix_fmt bgr24 -r 25 -i - \ -c:v libx264 -preset ultrafast -tune zerolatency -threads 8 ...
CPU encoding achieved 108 FPS throughput, completely unblocking the GPU render loop.
4. Visual Parity & Broadcast Quality#
Speed optimizations mean nothing if visual fidelity degrades. We evaluated the accelerated video against ground-truth rendering:
- Eye Stability: By combining
eye_f0_mode = Trueand , the anchor's gaze remains focused and alert, with zero fluttering or blink multiplication. - Phonetic Articulation: Lip movements with Kokoro female voice synthesis exhibit crisp bilabial closures and rounded vowels.
- Edge Seam Integrity: Sub-pixel FMA alpha blending across the canvas produces zero haloing or boundary seams on chroma key green screens.
| Frame 40 (Dynamic Vowel Viseme) | Frame 85 (Consonant Sibilant /s/) |
|---|---|
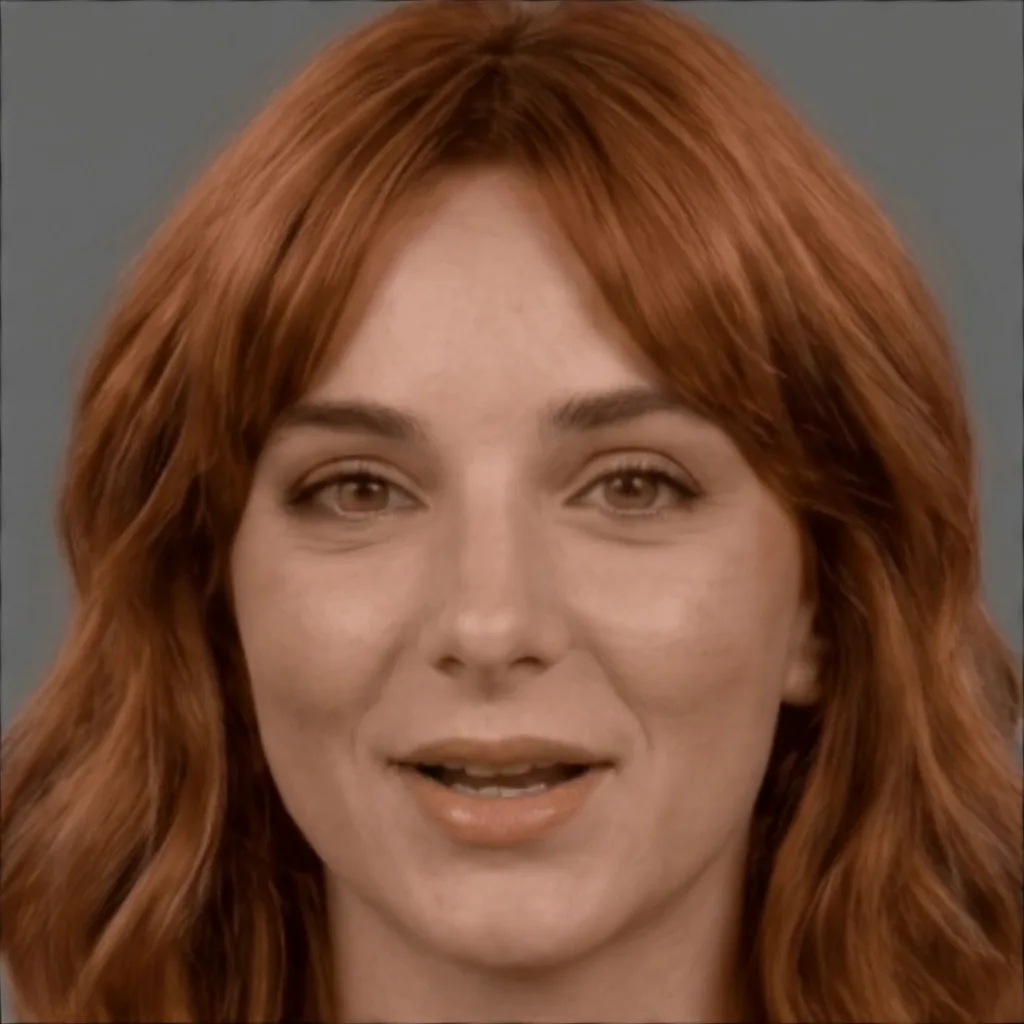 Click to zoomFrame 40 Real-Time Synthesis | 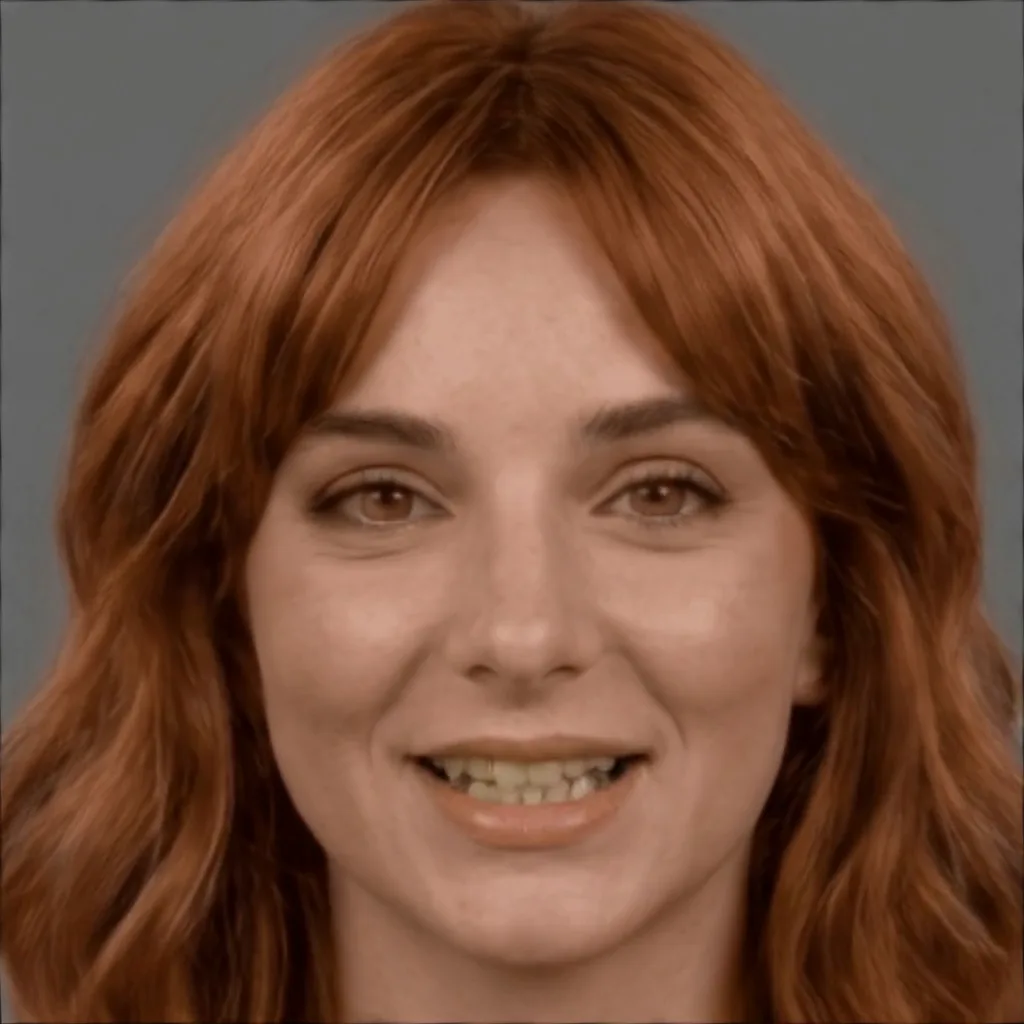 Click to zoomFrame 85 Real-Time Synthesis |
| Accurate oral cavity depth at 40.7 FPS | Sharp dental border geometry with zero blur |
5. Architectural Comparison: Ditto vs MuseTalk#
| Feature | MuseTalk 40FPS (NewsStudio) | Ditto Accelerated (NewsStudio) |
|---|---|---|
| Synthesis Scope | Lower Face ROI Patch | Full 3D Volumetric Head |
| Output Representation | 2D Latent Tile ( floats) | 3D Feature Field ( floats) |
| Head & Neck Motion | Static Base Frame Loop | Dynamic 3DMM Continuous Rotation |
| Inference Engine | TensorRT FP8/FP16 Inpainting UNet | PyTorch 2.13 CUDA Graphs SPADE Decoder |
| Render Throughput | ( real-time) | ( real-time) |
| Primary Use Case | Ultra-Low Latency Live News Desk | High-Expressivity Feature Anchors & Interviews |
6. How to Run#
bash# Run Accelerated Ditto Inference (40.7 FPS on RTX 5090) python scripts/ditto/run_preprocessed_ditto.py \ --avatar_dir /app/cache/avatars/ditto/ruby_burgundy \ --audio_path /app/cache/ruby_female_speech.wav \ --output_path /app/cache/ruby_ditto_accelerated.mp4 \ --batch_size 4 \ --vram_resident \ --silence_bypass # Run Full 4-Stage Comparative Benchmark Suite python scripts/ditto/benchmark_end_to_end_accelerated.py \ --avatar_dir /app/cache/avatars/ditto/ruby_burgundy \ --audio_path /app/cache/ruby_female_speech.wav