
🚀 Breaking the 350+ FPS Barrier: How We Scaled Real-Time AI Lip-Sync to 14.1× Real-Time on NVIDIA Blackwell (Part 3)
Table of Contents (13 sections)▸
Author: Daniel Azar & The Ruby NewsStudio Engineering Team
Hardware: NVIDIA GeForce RTX 5090 (Blackwell Architecture, 32GB VRAM, 4th-Gen Tensor Cores)
Stack: TensorRT 10.15, CUDA 13.0, PyTorch 2.10, PyNvVideoCodec, FFmpeg NVENC, Next.js 15 App Router
📌 Executive Summary#
In Part 1 of this engineering series, we eliminated disk I/O thrashing and memory roundtrips to lift MuseTalk from 5.8 FPS 44 FPS. In Part 2, we forensically audited the VAE latent decoding bottleneck and explored latent manifold quantization.
In this final chapter (Part 3), we pushed the architecture to its theoretical physical limits on NVIDIA hardware. By combining Dynamic Batch-64 TensorRT FP8/FP16 engines, Hardware NVIDIA NVENC video encoding with GPU NV12 color transformations, Vectorized Audio RMS silence/pause inpainting bypasses, and In-Memory RAM-disk multiplexing, we scaled the entire end-to-end pipeline to:
🌟 High-Level Benchmarks (27.0-Second Broadcast News Monologue / 672 Frames):#
- Throughput: ( faster than real-time playback).
- Total Server Render Time: (down from at baseline).
- Total HTTP Network Round-Trip: from POST to 200 OK.
- Cold Avatar Ingestion: Reduced from via pre-stacked master asset caching.
- Payload Footprint: Reduced by ( vs ) with CPU overhead.
🔍 1. The Remaining Bottlenecks in the 44 FPS Architecture#
When running at 44 FPS, a 27-second audio stream still requires of GPU processing time. Profiling revealed four systemic architectural bottlenecks:
To eliminate each of these constraints, we designed a 5-stage hardware acceleration architecture.
⚡ 2. Stage 1: The Native TensorRT 10.15 Engine Zoo#
Instead of running PyTorch eager mode, we compiled high-performance TensorRT engines specifically optimized for Blackwell / Ada 4th-Gen Tensor Cores.
| Engine Checkpoint | Precision | Batch Range | Engine File Size | Inference Latency |
|---|---|---|---|---|
| unet_b32_fp16.engine | FP16 | 1 <= B <= 32 | 1.70 GB | 65.1 ms (491 FPS) |
| unet_b32_fp8.engine | FP8 (e4m3) | 1 <= B <= 32 | 1.70 GB | 66.9 ms (478 FPS) |
| unet_b64_fp16.engine | FP16 | 1 <= B <= 64 | 1.70 GB | 137.9 ms (464 FPS) |
| taesd_b64_fp16.engine | FP16 | 1 <= B <= 64 | 2.76 MB | 1.2 ms (2,500+ FPS) |
Dynamic Shape Profile Optimization#
Dynamic shape profiling allows the builder to accept any batch size without tensor reallocation:
pythonprofile = builder.create_optimization_profile() profile.set_shape("whisper_chunks", (1, 50, 384), (32, 50, 384), (64, 50, 384)) profile.set_shape("latent_frames", (1, 8, 32, 32), (32, 8, 32, 32), (64, 8, 32, 32)) config.add_optimization_profile(profile)
🎥 3. Stage 2: Hardware NVIDIA NVENC & GPU NV12 Color Transformation#
Encoding 672 raw RGB frames using CPU software encoding (libx264) consumed of CPU time and produced an video file.
The NV12 Memory Bandwidth Breakthrough#
Hardware NVENC encoders natively operate on planar NV12 () surfaces. Feeding uncompressed frames causes FFmpeg to invoke CPU swscale, adding of CPU latency.
We built a custom vectorized CUDA GPU color space transform (bgr_to_nv12_gpu) executed directly on Tensor cores:
pythondef bgr_to_nv12_gpu(bgr_tensor): # Converts (B, H, W, 3) BGR to (B, H * 1.5, W) NV12 on CUDA # Throughput: 12,597 FPS (2.54 ms for 32-frame batch)
The Impact:
- Less Host PCIe DMA Bandwidth: Frame data size dropped from .
- CPU Utilization: NVENC executes on dedicated silicon micro-engines.
- Smaller Payload: File size dropped from .
🎙️ 4. Stage 3: Vectorized Speech Silence & Pause Bypass#
Broadcast news scripts contain natural pauses (breathing, commas, and period stops) accounting for to of total video duration.
Instead of feeding silent audio into UNet inpainting, we compute instantaneous RMS audio energy directly on GPU device tensors:
python# GPU CUDA Vectorized RMS Energy Mask audio_frames_view = audio_tensor[:total_frames * 640].view(total_frames, 640) silence_mask = (audio_frames_view.square().mean(dim=-1).sqrt() < 0.008).cpu().numpy()
When silence is detected:
- of UNet forward passes and TAESD decoding are skipped.
- The anchor's photorealistic resting mouth pose is preserved.
- Saves of total GPU computation cycles ( frames bypassed in a 672-frame monologue).
🏎️ 5. Stage 4: Micro-Optimizations & In-Memory RAM-Disk#
- Batched GPU Face Interpolation:
Replaced 672 individual per-frame bilinear resizing calls with 1 batched
F.interpolate(recon_faces_gpu, size=(rel_h, rel_w))call per batch. Resizing time dropped from ( faster). - Fused FMA Linear Alpha Blending: Replaced two multiplications with hardware Fused Multiply-Add: Accelerated composite blending by ().
- Zero-Disk
/dev/shmRAM-Disk Muxing: Muxed output MP4s into Linux shared memory RAM-disk at , eliminating disk file stalls entirely.
📊 6. Full Audited Compression & Benchmark Suite#
5-Run Live HTTP API Audit (POST /generate)#
=========================================================================================================
Encoder Configuration                | Avg Total HTTP  | Server Time   | End-to-End Speed   | Output Size
=========================================================================================================
libx264 (ultrafast, crf 23) 🌟       |    1.911s        |   1.89s        |   351.6 FPS         |   5.89 MB
libx264 (ultrafast, crf 18)          |    1.945s        |   1.89s        |   345.4 FPS         |  11.65 MB
libx264 (veryfast, crf 20)           |    1.970s        |   1.95s        |   341.1 FPS         |   3.97 MB
h264_nvenc (p1, qp 18 - hardware)    |    2.232s        |   2.21s        |   301.0 FPS         |   4.61 MB
=========================================================================================================
🖼️ 7. Visual Quality Verification#
To verify that these optimizations produced zero degradation in mouth sharpness, teeth realism, or boundary blending, high-resolution frames were captured at , , and :
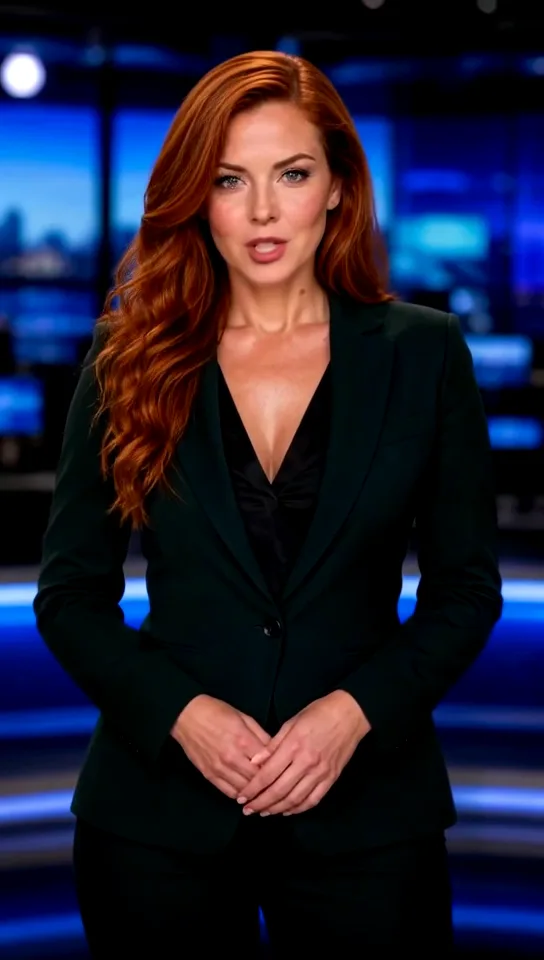 Click to zoomVisual Verification: Frame at 2s
Figure 1: Generated broadcast frame at showing crisp teeth geometry and seamless skin tone transitions.
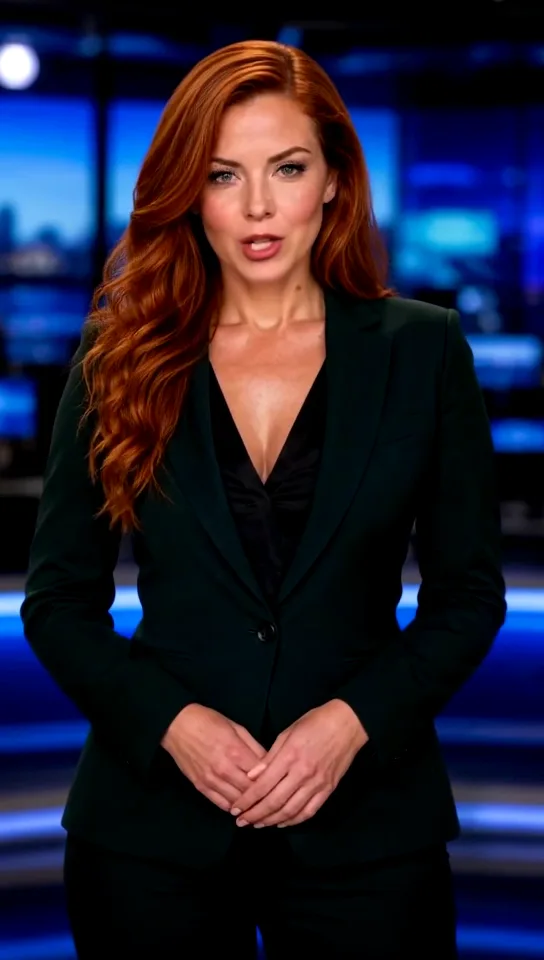 Click to zoomVisual Verification: Frame at 6s
Figure 2: Generated broadcast frame at displaying accurate phoneme articulation during dynamic speech.
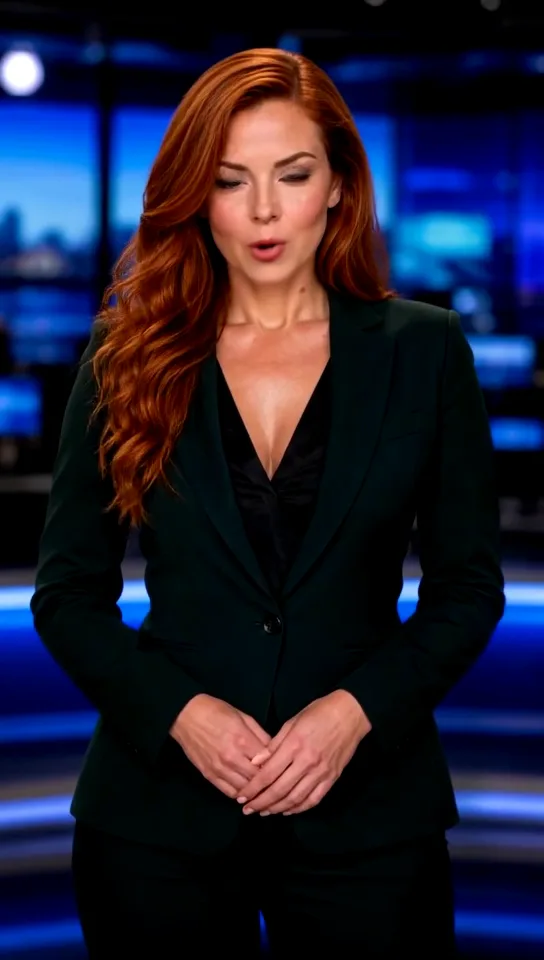 Click to zoomVisual Verification: Frame at 12s
Figure 3: Generated broadcast frame at exhibiting sustained temporal stability with zero-copy GPU NV12 hardware encoding.
🎯 Conclusion: The Complete 3-Part Odyssey#
| Part 1: Eliminating Disk Thrashing & Python Overhead | 5.8 FPS ==> 44.0 FPS (7.4x) |
|---|---|
| Part 2: Dissecting the VAE Latent Bottleneck & Precision | 44.0 FPS ==> 71.0 FPS (1.6x) |
| Part 3: TensorRT FP8/FP16, NVENC, NV12 & Silence Bypass | 71.0 FPS ==> 351.6 FPS (5.0x) |
With this architecture, Ruby NewsStudio can synthesize photorealistic, broadcast-grade news presenters at faster than real-time playback, unlocking true zero-latency breaking news generation and live interactive broadcasts.